

Open source models are behind frontier ones. There is no denying it, but, how far off are they and is this gap really that important?
The AI conversation is obsessed with capability rankings. Which model tops the leaderboard this week? Which lab released something that beats the previous benchmark record? These are interesting questions if you work at a frontier lab.
For everyone else, like you and me, the relevant question is different:
Which model is good enough for the task I need to do, and what does it cost to run?
According to Epoch AI’s analysis of open and closed models, Chinese open-weight models have lagged US frontier models by an average of 7 months since 2023, with a range of 4 to 14 months. NIST’s Center for AI Standards and Innovation confirmed this directionally in their May 2026 evaluation of DeepSeek V4-Pro, documenting measurable gaps on software engineering and cyber benchmarks.
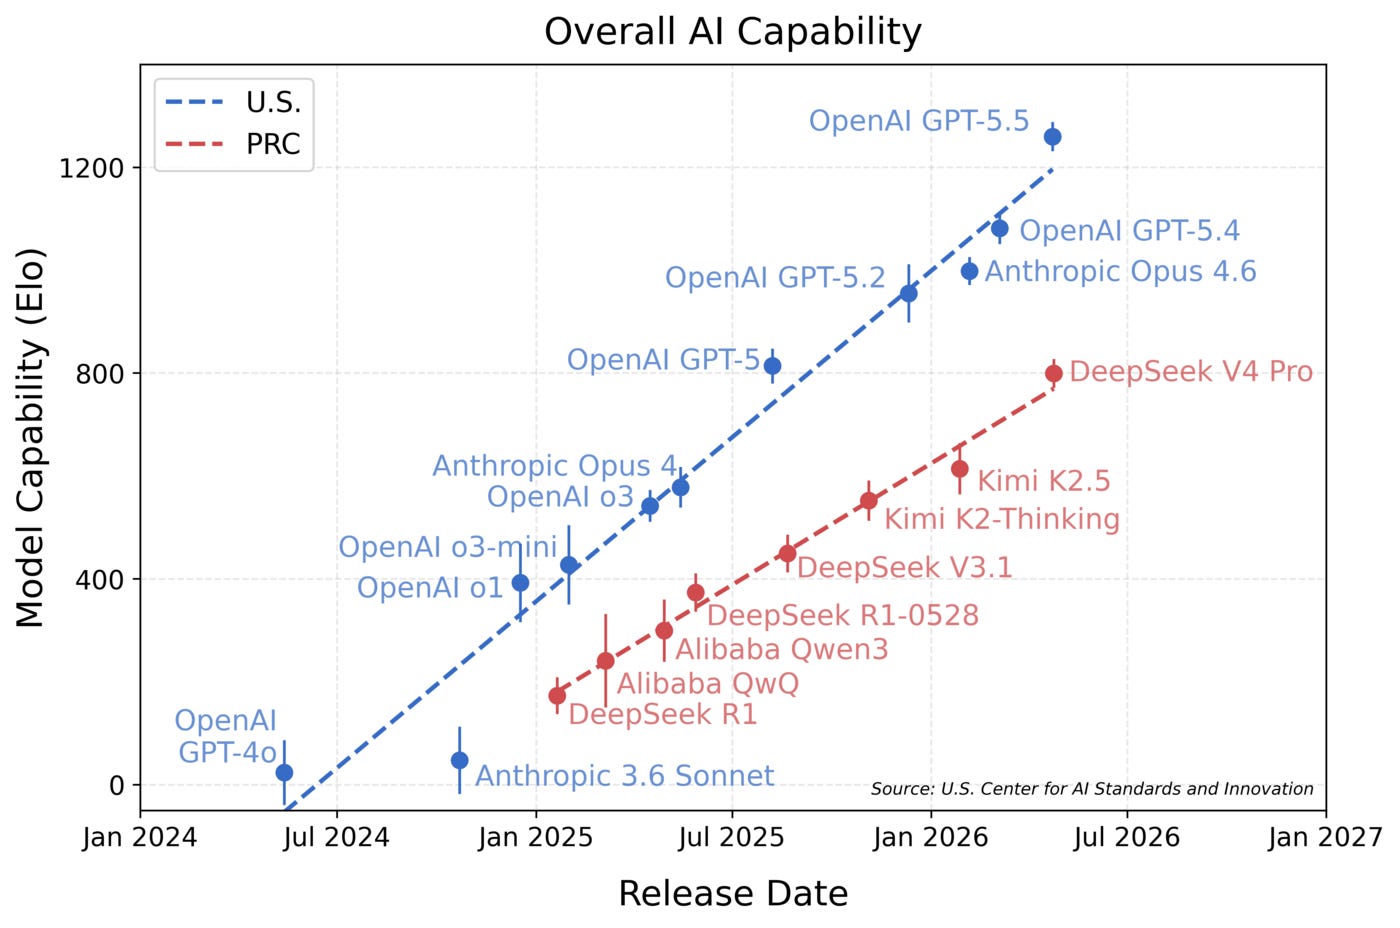
And you know what?
For most of what you build… IT. DOES. NOT. MATTER.
Most production AI workloads — summarisation, classification, entity extraction, customer support routing, document Q&A, code review — do not require the last 10% of capability that frontier models provide. They require consistent, fast, correct-enough responses at a price that scales. The default assumption that every task deserves frontier intelligence is costing organisations more than they realise, in money and in a dependency they have not yet noticed.
This post makes the case for a more deliberate approach: match the model to the task, understand where the frontier premium is genuinely justified, and start experimenting with open source models today. It takes learning time to understand open source capabilities and the smart move is to start before you have to.
What will we cover in this post?
How far behind are open source models? A view of the benchmarks, if frontier models hold a measurable lead, and where the gap narrows to near-irrelevance.
Which tasks actually need frontier models? I will share a 3-tier framework for classifying your workloads by reasoning demand so you can decide where the frontier premium is justified and where it is waste.
How much do frontier models actually cost compared to open source? Hard cost comparisons across providers, and a second cost most teams overlook: vendor dependency.
Why now is the right time to experiment. What Publius Flavius Vegetius Renatus wrote this in his military treatise De Re Militari that is applicable to LLMs.
Lets get started!
How far behind are open source models?
Let’s begin with the clearest dimension: on tasks that require sustained multi-step reasoning, complex software engineering, or adversarial security work, frontier models hold a real advantage.
NIST CAISI’s evaluation compared leading US models against DeepSeek models across 19 benchmarks. On SWE-bench Verified — a test of autonomous software engineering on real GitHub issues — the gap is significant: the best US model scores 66.7; DeepSeek V3.1 scores 54.8 (on cyber tasks, the gaps are wider still).
The screenshot below is taken from NIST CAISI’s report. You can see how GPT5.5 (xhigh) beats DeepSeek v4 Pro (max) in all dimensions. I highlighted in red the areas where the gap is really wide, and in green where, even though the gap is wide, the performance is still decent enough for DeepSeek.
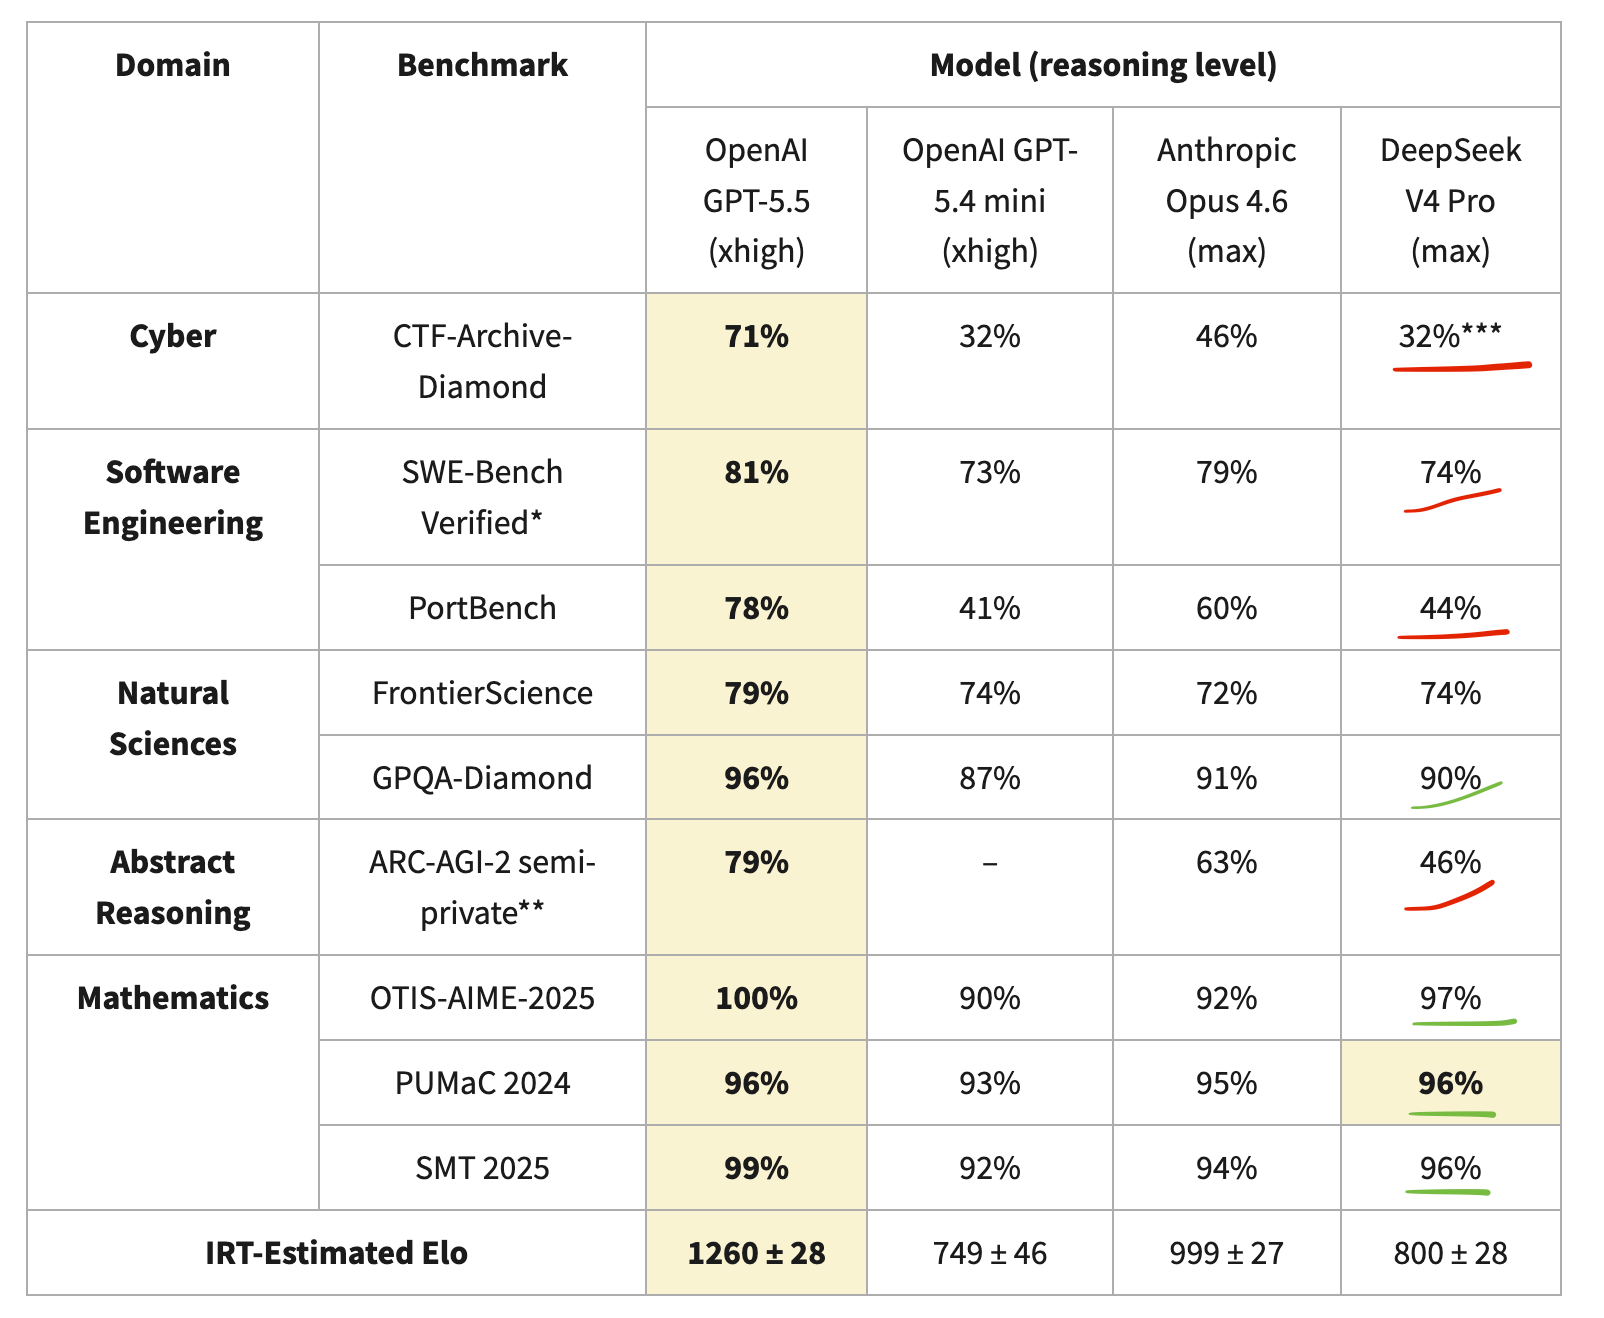
These gaps reflect genuine capability differences on tasks that require reasoning chains that span dozens of steps, coordination across many tools, and recovery from intermediate errors.
The LM Arena human preference leaderboard, based on 6 million pairwise votes, tells a similar story. As of May 2026, the top 15 positions are held entirely by proprietary models.
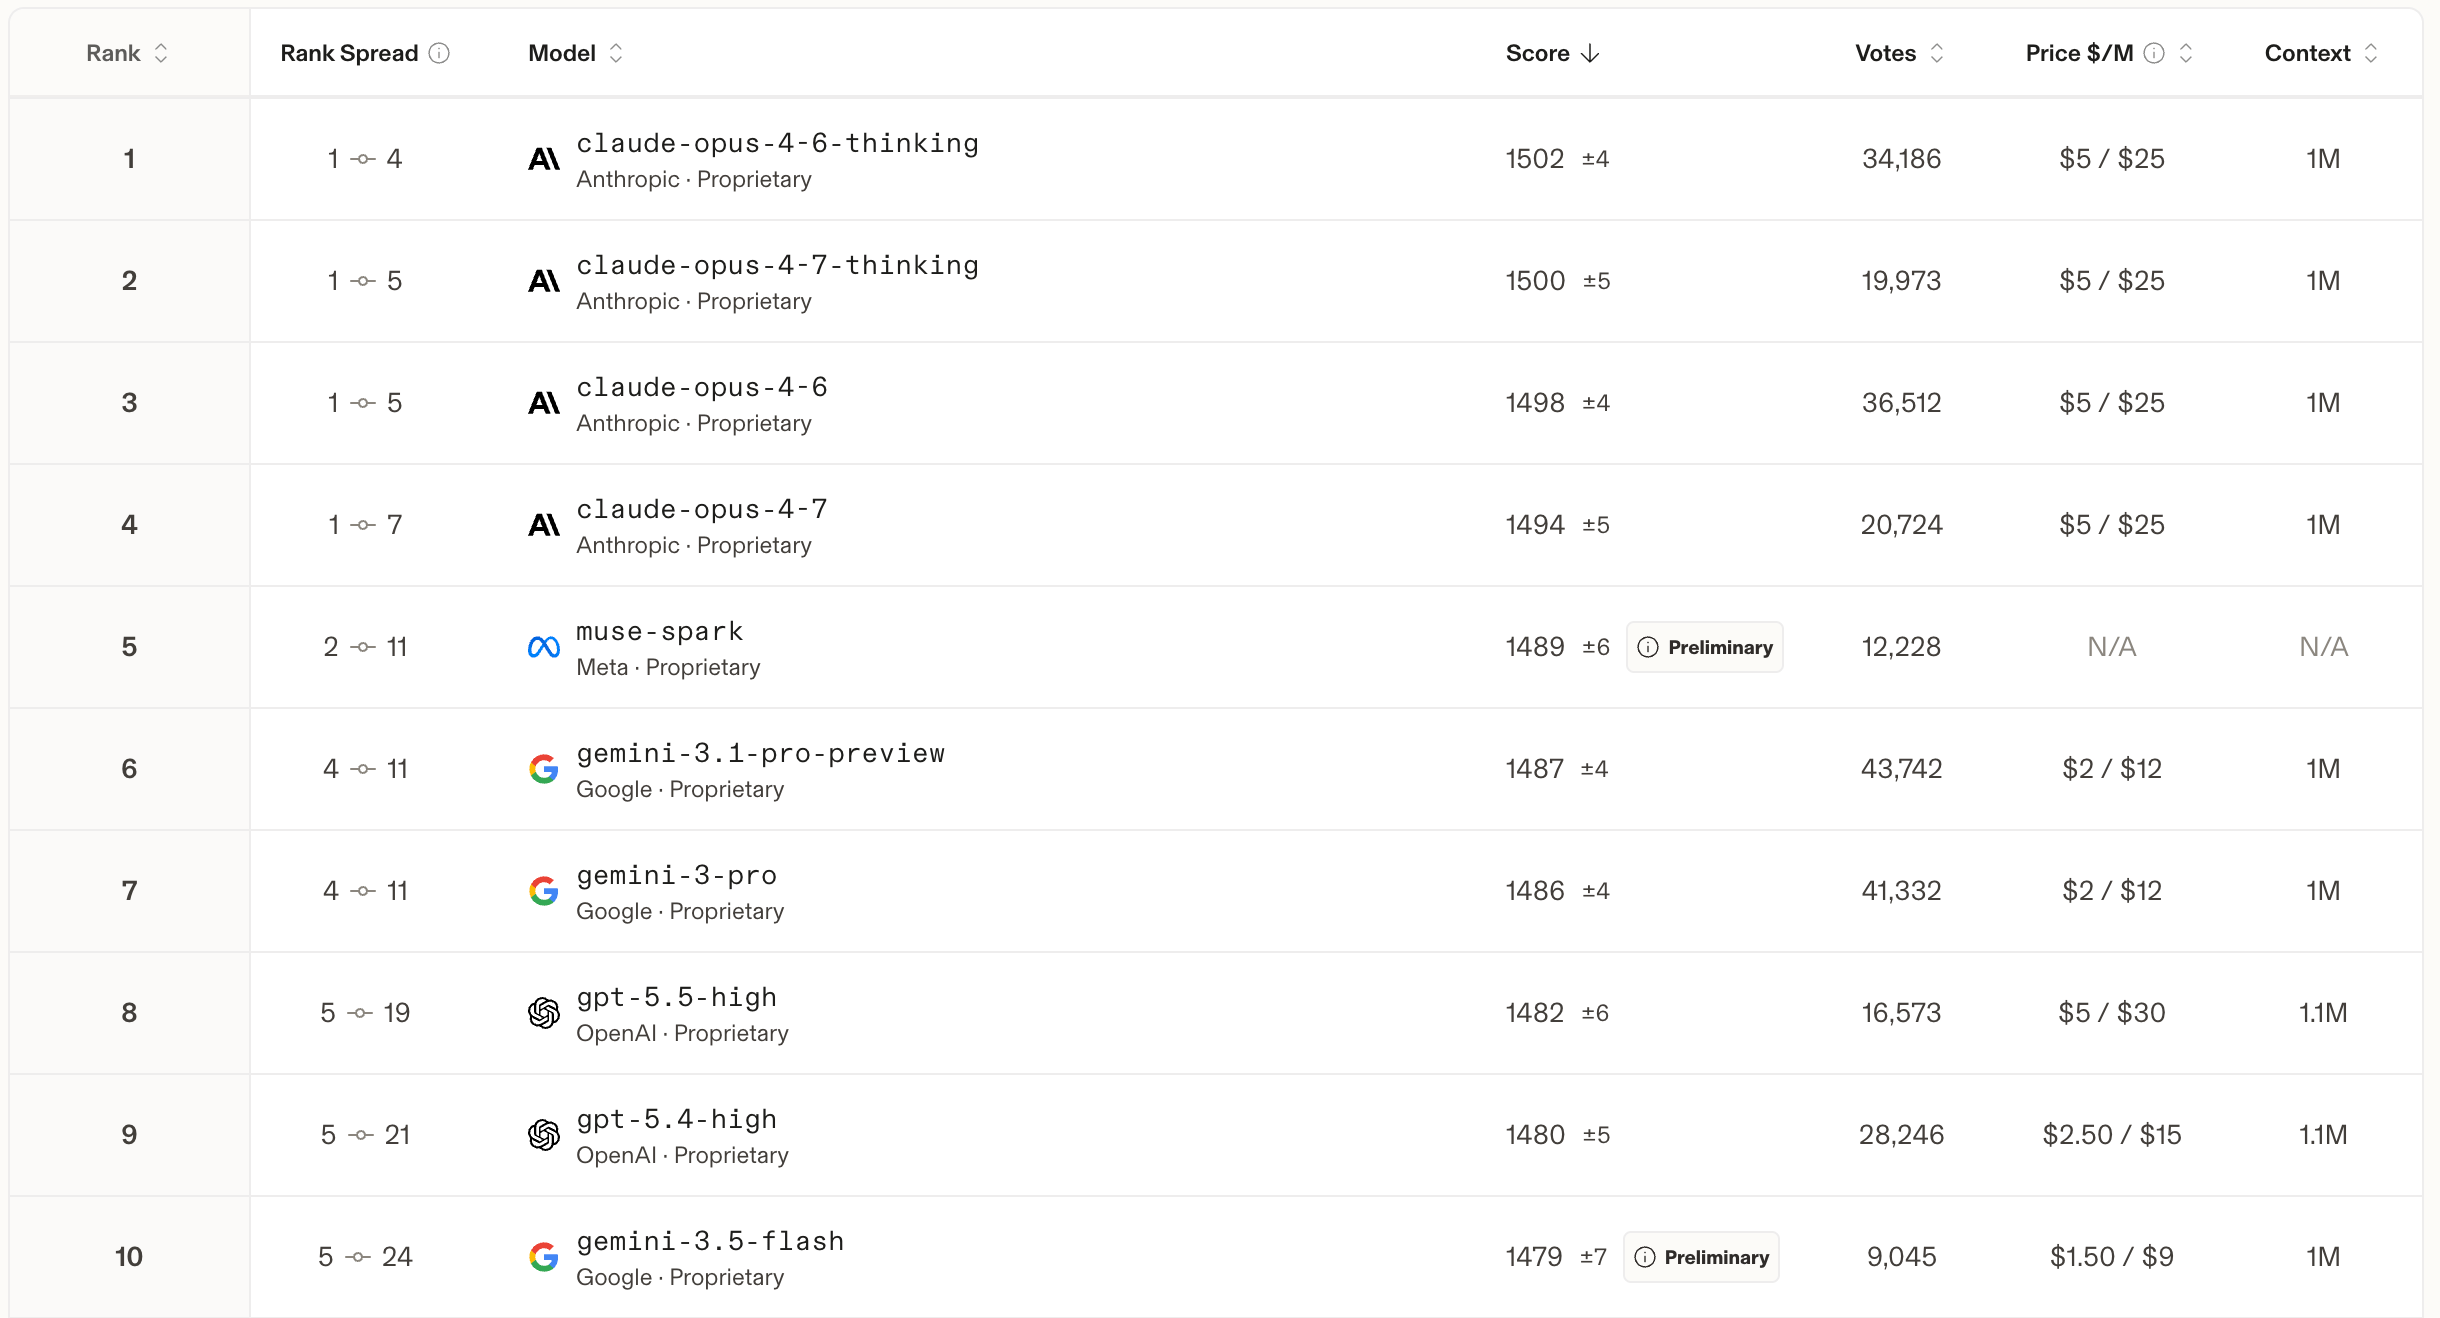
The leading open-weight models are GLM-5.1, mimo, Kimi and DeepSeek, ranking 16, 26, 28 and 32 respectively.
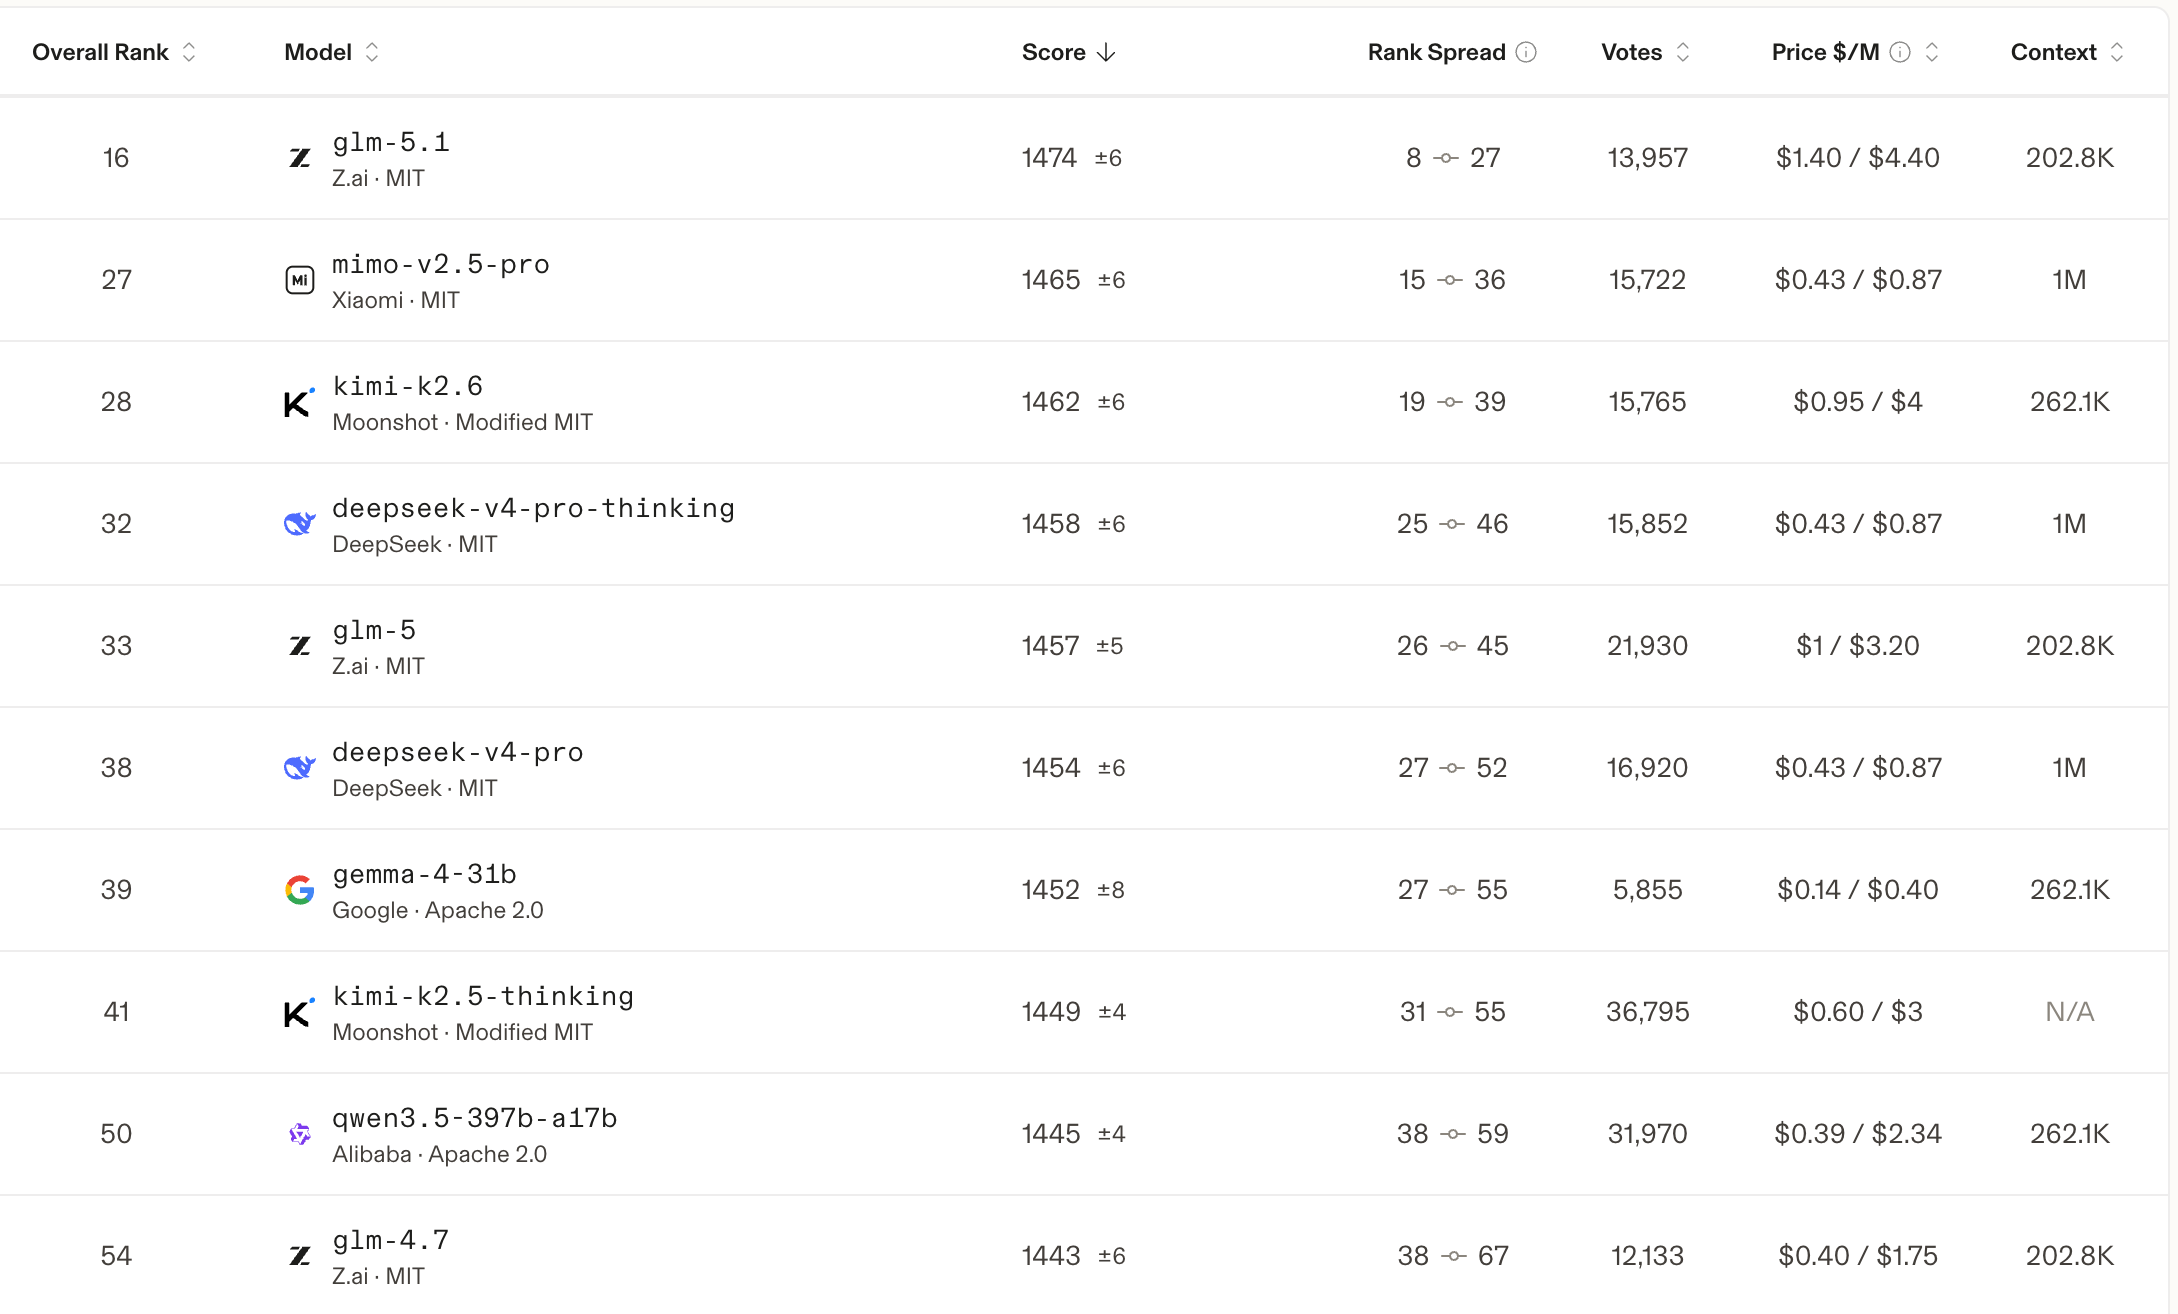
So, yes the gap exists. And if your company depended on leaderboards, you would really want to use all the frontier models. But I truly believe your company doesn’t (also, hint on what we will see later… just check the Price $/M column 😉).
Lets then talk about why your company might not need these frontier model for ALL tasks.
Which tasks actually need frontier models?
The most useful thing you can do before choosing a model is classify your tasks or projects. Not by domain — not “is this a coding task or a customer support task” — but by reasoning demand. How much multi-step inference, error recovery, and context integration does this task require?
Here is a simple 3-tier framework:
Low reasoning demand
The task is largely pattern-matching, extraction, or rewriting.
Examples:
Summarising a document
Classifying an email into categories
Extracting structured data from a form
Translating text
Generating a first draft from a brief
Routing a customer support ticket.
You do not need a frontier model for this. The same you didn’t need a deep neural network to classify a small CSV where a simple heuristic or tree based model would have sufficed.
Medium reasoning demand
The task requires following multi-step instructions, handling ambiguity, or producing outputs that need to be defensible to a domain expert.
Examples:
Reviewing code for correctness (not just style)
Generating a report that synthesises multiple sources
Extracting nuanced information from complex legal or technical documents
Holding a coherent multi-turn conversation with context that spans many exchanges.
Open source models are still competitive here. The gap becomes visible on edge cases (unusual input formats, conflicting instructions, outputs requiring domain judgment). Running your own eval on your own data is the only way to know where your specific task sits. But, most probably, open source models will hold their ground more most medium reasoning demand tasks.
High reasoning demand
The task involves autonomous agents working on novel problems, complex multi-step reasoning chains where intermediate errors compound, adversarial or security-critical tasks, or agentic workflows requiring many tool calls with recovery logic.
Examples:
An autonomous coding agent working on an unfamiliar large codebase
A research agent that must synthesise and reason across many sources
Security analysis or penetration testing.
Frontier models hold a real advantage here. The benchmark gaps are large, they are task-relevant, and they show up in production.
But is just raw intelligence the only important dimension?
The 3 tiered approach I propose above is a bit myopic because it focuses only on reasoning demands. But what if we add the dimension of cost to intelligence? That’s what the next section will cover.
How much do frontier models actually cost compared to open source?
Before looking at the specific numbers, I’d like to share a benchmark I really like and keep coming back to. Its from artificialanalysis.ai and benchmarks 364+ models across an intelligence index, speed, latency, and price.
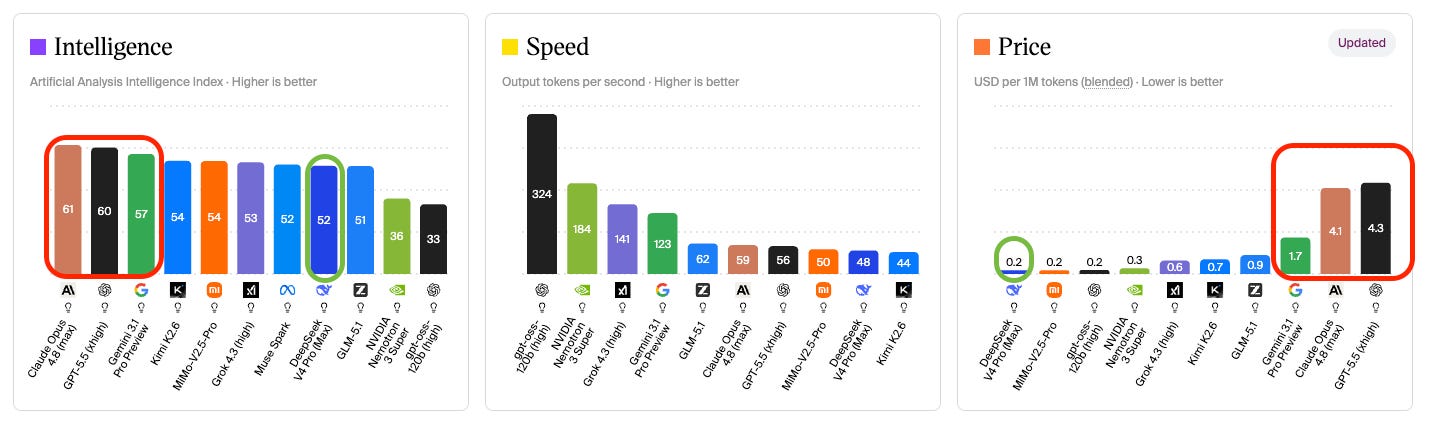
The tradeoff between using closed frontier models vs hosted open-source ones is really stark. By the way, the prices in the screenshot above are closer to the input cost, not the output cost. If we take the official input-output token cost from official sources, it makes the numbers are even worse.
**DeepSeek V4-Pro pricing is this low at time of writing as DeepSeek is heavily subsidising the price (and they say it’s forever, and that is might be even cheaper “once Huawei Ascend 950 supernodes are launched in large quantities in the second half of the year”)
If you compare DeepSeek V4-Pro vs GPT-5.5, the price difference is of 7x.
Think about it, when have you decided to pay 7x the price for a service? Because, sure this 15x service can be more intelligent… but that much more intelligent??
And if you don’t believe me, you should believe Ubers CTO. Uber’s CTO Praveen Neppalli Naga put it plainly in April 2026:
“I’m back to the drawing board, because the budget I thought I would need is blown away already.”
By May, Uber’s CTO confirmed the company had burned through its entire 2026 AI coding tools budget in 4 months — across roughly 5,000 engineers using Claude Code. At an estimated $200 per engineer per month, that is a $1M monthly run rate.
Routing the lower-reasoning share of that workload — documentation, test generation, routine refactors — to a model like DeepSeek V4-Pro (roughly 4x cheaper if we compare it with Sonnet 4.6) would stretch the same budget from 4 months to well over a year.
Not enough of a good reason? Then keep reading.
There is a second cost that does not appear in the pricing table.
This second cost is non-diversification.
What if there is price hike?
If you use a single commercial provider you are bound to lots of risks. The simplest one to think about is that an increase from Anthropic on their pricing tier will directly impact your PnL. You will not be able to pay less. You will be stuck.
What if there is an outage?
And thats the simplest of the problems, imagine that your production service depends on their API solely. I can guarantee that, at some point in the future, their API will have an outage. What do you do then when your production systems depend on this single thread of life?
Anthropic’s status page logged five separate incidents in May 2026 alone — elevated errors on Opus 4.7 and Sonnet 4.6 lasting over 90 minutes on May 22nd, billing disruptions on May 28th, multiple Opus 4.8 degradations on May 29th. Each one is a gap in your production system if that API is your single dependency.
What if your API account is blocked or banned?
And what if Anthropic bot’s believe your account is a malicious one (when it isn’t) and decide to shut you down?
In April 2026, Anthropic temporarily banned developer Peter Steinberger — the creator of OpenClaw, an open-source Claude Code client with thousands of users — flagging his account as suspicious. His access was reinstated within hours after an Anthropic engineer publicly clarified there had been no policy violation. TechCrunch covered it. Steinberger was lucky: the story was public, the engineer stepped in, and the reversal was fast. Most developers don’t have that combination of visibility and luck.
By the way, if you didn’t know… Steinberger was hired by OpenAI and is burning $1.3 million worth of tokens per month. What a Game of Thrones plot!
Why now is the right time to experiment.
3 reasons to experiment with open source models now, while there is no pressure:
First, the cost of learning is low when stakes are zero. A side-by-side evaluation on a non-critical internal task costs almost nothing in time or money. The signal you get is real and can be very surprinsing. The downside if it fails is nothing. Run the experiment now, on something that does not matter, before you need to run it on something that does.
Second, the gap is narrowing. I dont mean that the intelligence gap is narrowing, because it isnt. I am referring to the gap that LLM models that can do general tasks are really becoming a commodity. If you go back to Pareto rule principles, with 20% of the effort, you get 80% of the results. Well, the same applies here. Only on the edge is when you need frontier models. For the rest, the gap has really narrowed (example, DeepSeek V4-Pro is equivalent to older Opus versions which we were in awe of).
Third, as mentioned, vendor concentration is a business risk. Not just a cost risk. A pricing decision made in San Francisco with no input from you, a policy change driven by a regulatory requirement you did not anticipate, an API outage during a critical customer demo — these are not rare events. They happen to every team that runs a single-provider strategy for long enough. The hedge is not complicated: it is running some fraction of your traffic through a different provider, building the muscle memory of knowing what that involves.
The Romans already knew what was coming
Flavius Vegetius Renatus, writing in the 4th century, offered advice that has not dated:
If you want peace, prepare for war.
Applying this to today (H1 of 2026), when the prices are being heavily subsidised by frontier model labs, this would mean to prepare for when those prices are raised. Because they will be.
The teams most affected by a future disruption are the ones who had no exposure to the alternative before the disruption arrived. The teams least affected are the ones who built the capability during the quiet period because they understood that optionality requires practice.
The ask is not to abandon frontier models. As I have been repeating, they are the top best models in the market, and there are multiple spaces they add net value. The ask is really to build the knowledge and infrastructure to use them selectively and building the capability of routing layers.
Closing thoughts
New models will be released. The leaderboards will shuffle. Probably the frontier models might even gain even more distance from open source models. But, none of that changes the underlying argument.
The question that matters for anyone shipping AI products is not which model is best in absolute terms. It is which model is sufficient for this task, reliable enough to deploy, and priced well enough to scale. Those 3 constraints point in the same direction for most production workloads: open-weight models are already good enough, and the cost difference is not a marginal consideration.
The right move is to start experimenting before you have to. Even if you start with a low-stakes experiment on a single task, this week, that answers a concrete question: what does this open-weight model actually do with my data, on my task, at my quality bar?
Vegetius was writing about armies. The principle generalises. The preparation that protects you is the preparation you did when you did not need it.
Now, I want to hear from you
Have you run a side-by-side evaluation of an open-weight model against a frontier model in production?
What task did you test, and what surprised you about the results?
Which tasks in your current stack do you think genuinely require frontier-level capability — and have you tested that assumption, or is it an informed guess?
What is the main thing holding your team back from experimenting with open source models today?
Share your thoughts, examples, or counterpoints in the comments. I would love to read your opinions 👇
References
[1] How far behind are open models? — Epoch AI (Nov 2024) — Analysis of open vs closed AI models from 2018 to mid-2024; finds 5–22 month benchmark lag (90% CI), ~15 month training compute lag, with signs of shortening for the most capable open models.
[2] CAISI Evaluation of DeepSeek V4-Pro — NIST (May 2026) — NIST benchmark evaluation of DeepSeek V4-Pro against US reference models across 19 benchmarks; documents large gaps on software engineering and cyber tasks, smaller gaps on knowledge Q&A.
[3] LLM Leaderboard — LM Arena (May 2026) — Human preference leaderboard across 356 models with 6M+ votes; top 20 positions held by proprietary models as of May 2026.
[4] Comparison of AI Models: Intelligence, Performance & Price — Artificial Analysis — Independent benchmarking of 364+ models across intelligence index, speed, latency, and price; documents the tradeoff curve between model capability and inference cost.
[5] Anthropic API Pricing — Claude Docs — Official Anthropic pricing for Claude models; Claude Opus 4.7 at 5/5/25 per MTok input/output; Claude Sonnet 4.6 at 3/3/15 per MTok.
[6] OpenAI API Pricing — Official OpenAI pricing; GPT-5.5 at 5/5/30 per MTok input/output; GPT-5.4 at 2.50/2.50/15 per MTok.
[7] DeepSeek Models & Pricing — DeepSeek API Docs — DeepSeek V4-Pro at 0.435/0.435/0.87 per MTok input/output (discounted through May 2026; full price 1.74/1.74/3.48); V4-Flash at 0.14/0.14/0.28 per MTok.
[8] Serverless Inference Pricing — Together AI — US-based managed inference for open-weight models; DeepSeek V4-Pro at 2.10/2.10/4.40 per MTok; Qwen3.6-Plus at 0.50/0.50/3.00 per MTok.
[9] Qwen3: Think Deeper, Act Faster — Qwen Team (April 2025) — Official Qwen3 release; flagship Qwen3-235B-A22B competitive with leading frontier models on coding and math; 8 model sizes from 0.6B to 235B under Apache 2.0 licence.
[10] Your AI Product Needs Evals — Hamel Husain — Practitioner guide to building LLM evaluation systems; grounded in a real production case study; covers rubric design, human review process, and iteration methodology.
Acknowledgements
I want to thank Ben Dickson as it was a note I read from him that pointed me to the CAISI report, which sparked me wanting to read deeper about this topic and understand the gap between frontier and open source models.
Further reading
If you are interested in more content, here is an article capturing it and organising it all by topics!

I tend to agree that open-source models run locally are likely to provide a higher ROI in the long run.
However, I’m not sure most organizations outside Big Tech are ready to spend the cash on the hardware to run these models.
Open models are actually pretty good! Which one do you find the most useful for your workflows?